 ™
In this chapter, we explain how you can install RDF4J Server (the actual database server and SPARQL endpoint service) and RDF4J Workbench (a web-based client UI for managing databases and executing queries).
RDF4J Server and RDF4J Workbench requires the following software:
We recommend using a recent, stable version of Apache Tomcat (version 9.0) or Jetty (version 9.4)
The quickest way to get RDF4J Server and Workbench running locally is to use the Docker environment included in the docker/ directory of the source distribution. It builds the project, packages it into a Docker image, and starts it via Docker Compose.
All commands below are run from that directory:
cd docker
./run.sh
This script builds the Maven project, assembles the SDK, builds the Docker image, and starts the container. Once ready it prints:
Workbench is available at http://localhost:8080/rdf4j-workbench
By default Apache Tomcat is used. To use Jetty instead, set APP_SERVER before running:
APP_SERVER=jetty ./run.sh
| Application | URL |
|---|---|
| RDF4J Server | http://localhost:8080/rdf4j-server |
| RDF4J Workbench | http://localhost:8080/rdf4j-workbench |
Follow logs in real time:
docker compose logs -f
Stop the container (data volumes are preserved):
docker compose stop
To stop the container and remove the image and all volumes:
./shutdown.sh
RDF4J Server is a database management application: it provides HTTP access to RDF4J repositories, exposing them as SPARQL endpoints. RDF4J Server is meant to be accessed by other applications. Apart from some functionality to view the server’s log messages, it doesn’t provide any user oriented functionality. Instead, the user oriented functionality is part of RDF4J Workbench. The Workbench provides a web interface for querying, updating and exploring the repositories of an RDF4J Server.
If you have not done so already, you will first need to download the RDF4J SDK. Both RDF4J Server and RDF4J Workbench can be found in the war directory of the SDK. The war-files in this directory need to be deployed in a Java Servlet Container. The deployment process is container-specific, please consult the documentation for your container on how to deploy a web application. For Apache Tomcat, we recommend using the Tomcat Manager to make deployment easier.
For Jetty, it’s just a matter of copying the war-files to $JETTY_BASE\webapps
After you have deployed the RDF4J Workbench webapp, you should be able to access it, by default, at path http://localhost:8080/rdf4j-workbench. You can point your browser at this location to verify that the deployment succeeded.
RDF4J Server RDF upload endpoints and Workbench’s Add upload accept RDF input compressed with gzip, zlib/deflate, BZip2, XZ, LZMA, framed LZ4, framed Snappy (.sz or .snappy), Unix compress (.Z), Brotli, or Zstandard. Compression is detected from a reliable stream signature when one exists and otherwise from the file-name suffix. The supplied Server and Workbench applications include the optional archive decoder libraries; using RDFLoader in an embedded application does not add those libraries as transitive runtime dependencies.
ZIP and TAR archives are traversed recursively. This includes conventional compressed TAR names such as .tar.gz, .tar.bz2, .tar.xz, .tar.lz4, and .tar.zst. Directories and special TAR entries are ignored. Regular members whose names identify an RDF format are parsed independently; unknown terminal members are skipped during automatic format detection, and an archive with no recognized RDF member is rejected. When an explicit RDF format is supplied, it is also used as the fallback for unnamed or otherwise unknown regular members.
These formats are automatic RDF input decoding, not additional HTTP content codings. The accepted Content-Encoding values and response compression negotiation are unchanged.
Decoder allocation is limited to 64 MiB by default. Set the Java system property org.eclipse.rdf4j.rio.compression.maxDecoderMemoryKiB to a positive KiB value to change that limit. The aggregate ZIP-and-TAR entry limit is 50,000 and can be configured with org.eclipse.rdf4j.rio.loader.max_archive_entries; the existing ZIP-specific limit remains in force as well.
There is a known issue affecting the proper exploring of resources that use an extended character set. Workbench client-side code generates URI’s assuming an ISO-8859-1 character encoding, and often Tomcat comes pre-configured to expect UTF-8 encoded URI’s. It will be necessary to change the HTTP Connector configuration, or to add a separate HTTP Connector that uses ISO-8859-1. For details, see the Tomcat 8.5 or Tomcat 9 documentation.
To resolve issues where the request body is not getting properly interpreted as UTF-8, it is necessary to configure Tomcat to use its built-in SetCharacterEncodingFilter. More details are available at the Tomcat wiki. Un-commenting the $CATALINA_BASE/conf/web.xml, and restarting the server, should be the only necessary steps.
The RDF4J Server and Workbench store configuration files and repository data in a single directory (with subdirectories). On Windows machines, this directory is %APPDATA%\RDF4J\ by default, where %APPDATA% is the application data directory of the user that runs the application. For example, in case the application runs under the ‘LocalService’ user account on Windows XP, the directory is C:\Documents and Settings\LocalService\Application Data\RDF4J\. On Linux/UNIX, the default location is $HOME/.RDF4J/, for example /home/tomcat/.rdf4j/. We will refer to this data directory as [RDF4J_DATA] in the rest of this manual.
The location of this data directory can be reconfigured using the Java system property org.eclipse.rdf4j.appdata.basedir. When you are using Tomcat as the servlet container then you can set this property using the JAVA_OPTS parameter, for example:
set JAVA_OPTS=-Dorg.eclipse.rdf4j.appdata.basedir=\path\to\other\dir\ (on Windows)
export JAVA_OPTS='-Dorg.eclipse.rdf4j.appdata.basedir=/path/to/other/dir/' (on Linux/UNIX)
One easy way to find out what the directory is in a running instance of the RDF4J Server, is to go to http://localhost:8080/rdf4j-server/home/overview.view in your browser and click on ‘System’ in the navigation menu on the left. The data directory will be listed as one of the configuration settings of the current server.
If you are using Apache Tomcat as a Windows Service you should use the Windows Services configuration tool to set this property. Other users can either edit the Tomcat startup script or set the property some other way.
On Linux systems, systemd may impose additional restrictions on the location of the data directory. If the server seems to have started successfully, but the [RDF4J-DATA] directory remains empty - i.e. no server nor workbench subdirectories are being created - the tomcat service configuration needs to be adapted.
For example: Tomcat 9 on Debian with /var/rdf4j/ as the data directory requires an additional ReadWritePaths in the /etc/systemd/system/tomcat9.service file,
followed by a systemctl daemon-reload and systemctl restart tomcat9.service to apply this change.
 [Service]

ReadWritePaths=/var/rdf4j/
Workbench reads its flat workbench.properties policy once when the web application starts. Values are merged in this order, with later values taking precedence:
org/eclipse/rdf4j/common/app/config/defaults/workbench.properties.org/eclipse/rdf4j/common/app/config/workbench.properties.[RDF4J_DATA]/Workbench/conf/workbench.properties on Windows and macOS, or
[RDF4J_DATA]/workbench/conf/workbench.properties on Linux and other UNIX systems, where the application
directories are lower case (like the server and workbench directories mentioned above).The external file can hide Workbench pages and capabilities without changing the deployed WAR. It is read as UTF-8, so
labels can use any characters; a file that is not valid UTF-8 is read as ISO-8859-1, and \uXXXX escapes work in
both. Every key is validated when the Workbench starts: both the WAR and the Spring Boot runner load the Workbench at
application startup. An unknown key, undeclared ID, malformed boolean or order, unsafe href, or invalid theme is a
configuration error. It is logged as an error at startup, with the problem and the location of the external file. The
application keeps running, in Tomcat, Jetty and the Spring Boot runner alike (so an RDF4J Server deployed next to it is
not affected), but every Workbench page, including the Workbench root, answers 503 Service Unavailable with a
plain-text message that states the problem. The policy is read once, when the Workbench starts: after fixing the file,
restart the Workbench (or redeploy the WAR), as for any other change to workbench.properties. For example:
# Show only the repository list and Query, and explicitly disable Summary. Keep a Workbench landing page
# (repositories or server) visible: without one, the Workbench root answers 503 Service Unavailable.
menu.items=repositories,query
menu.groups=repositories,explore
menu.group.repositories.visible=true
menu.group.explore.visible=true
menu.item.query.order=10
page.summary.enabled=false

# Hide the Information page. Its route answers 404, like any other disabled page.
page.information.enabled=false

# Hide a whole navigation group or one item.
menu.group.modify.visible=false
menu.item.namespaces.visible=false

# Fix the query-result download default; zero means all rows.
query.feature.result-download-limit.enabled=false
query.download.default-limit=0

# Initial theme before the user has selected a preference.
theme.deployment-default=system
An embedding application can override the packaged settings without modifying RDF4J resources by adding
src/main/resources/org/eclipse/rdf4j/common/app/config/workbench.properties to its own classpath. For example, a
Spring Boot consumer can package this file in its application JAR:
menu.item.query.label=SPARQL workspace
menu.item.query.order=5
query.feature.result-wrap.enabled=false
theme.deployment-default=dark
That resource overrides the packaged defaults in both the Workbench WAR and Spring Boot integration. The external
workbench.properties file in the data directory has the final say when the same key appears in both overrides.
The built-in menu IDs are server, repositories, create, delete, summary, namespaces, contexts, types, explore, graph, query, saved-queries, export, update, add, remove, clear, and information. menu.items is a comma- or whitespace-separated list; an omitted built-in item is hidden. menu.groups lists groups in display order. Built-in group IDs are server, repositories, explore, modify, and system; the packaged defaults list and enable all five. A group must be listed and have menu.group.<id>.visible=true for its children to appear. The Workbench root and /repositories/ land on the repositories page, or on server when the repository list is hidden; when both are hidden they answer 503 Service Unavailable. Each item must also be listed and visible, and page.<id>.enabled can further disable its canonical page. A true page setting cannot restore an item or group hidden by another setting. Thus, adding a second menu link to /query does not make the Query page available when the built-in query item is omitted or hidden. The policy gates the canonical servlet behind every configured alias before proxy cache handling, redirects, or command dispatch. The raw /info endpoint remains available. Query and Update use the read-only /_internal/namespaces metadata route when the Namespaces page is hidden.
The optional item keys are menu.item.<id>.visible (true or false), .label, .order (integer, default 0), .group, .icon, .href, and .route. Group keys are menu.group.<id>.visible, .label, .icon, and .order (integer, default 0). Item order sorts numerically, then by position in menu.items, then by ID; group order follows the same rule using position in menu.groups. Hrefs may be HTTP(S) URLs or application-relative paths. Opaque schemes such as javascript: and protocol-relative URLs are rejected at startup. To add an embedded application’s page, list its ID in menu.consumer-ids, add it to menu.items, declare its group in menu.groups, enable the group, and provide the item’s .href; set .route when the endpoint path differs from the item ID. The page is then controlled by page.<id>.enabled in addition to its menu visibility.
Query capabilities use query.feature.<id>.enabled (true or false). These 47 built-in IDs are stable policy keys and map to the existing Workbench controls and operations:
| Feature ID | Controls or operation |
|---|---|
query-execution | Run a query and query-backed result downloads. |
query-language | Query language selector. |
query-save | Save-query controls and save operation. |
query-private-save | Save query privately. |
query-options | Named Query options disclosure. |
query-timeout | Query timeout. |
query-inferred-statements | Include-inferred option. |
query-explain | Explain action and server operation. |
explain-level-unoptimized | Unoptimized Explain level. |
explain-level-optimized | Optimized Explain level. |
explain-level-executed | Executed Explain level. |
explain-level-telemetry | Telemetry Explain level. |
explain-level-timed | Timed Explain level. |
explain-format-text | Text Explain format. |
explain-format-dot | DOT Explain format. |
explain-format-json | JSON Explain format. The Query page also uses JSON to transport Text explanations, so JSON requests stay allowed while explain-format-text is enabled. |
explain-highlight-syntax | Syntax highlighting for explanations. |
explain-highlight-hotspot | Hotspot highlighting for explanations. |
explain-property-selection | Explanation property selection controls. |
explain-view-text | Text explanation view. |
explain-view-dot | DOT graph explanation view. |
explain-view-json | JSON explanation view. |
explain-download | Download explanation. |
explain-copy | Copy explanation, including the compare-pane copy action. |
explain-cancel | Cancel control for a pending explanation. Disabling it hides the control only: the page still cancels explanations it abandons. |
query-compare | Open the comparison editor pane. |
query-diff | Show the explanation difference. |
query-swap | Swap the primary and comparison queries. |
result-layout | Tuple/graph result layout selection. |
result-wrap | Wrap long result values. |
result-totals | Display result totals. |
result-paging | Change result-page offset. |
result-page-size | Results-per-page selector. |
result-page-previous | Previous result page. |
result-page-next | Next result page. |
result-download | Download query results. |
result-download-format | Result download format selector. |
result-download-format-tuple | Tuple/boolean result download formats. |
result-download-format-graph | RDF graph result download formats. |
result-download-limit | Query-result download limit; 0 means all results. |
result-show-datatypes | Show datatype details in tuple results. |
result-fullscreen | Fullscreen for the result frame. |
query-rerun | Rerun an existing explanation. |
query-cancel | Cancel control for a running query. Disabling it hides the control only: the page still cancels queries it abandons, for example when you leave the page. |
editor-namespaces | Clear/reload editor namespaces. |
editor-sidebar | Toggle the query sidebar. |
editor-fullscreen | YASQE editor fullscreen button and F11 shortcut. |
Plan copying is controlled by explain-copy; query-copy and editor-reset are not built-in IDs because no matching actions are exposed. The built-in result-download-limit capability controls the query-results download-limit selector. Embedded applications declare additional stable feature IDs in query.consumer-feature-ids; unknown feature keys are rejected. query.download.default-limit is the fixed fallback value and defaults to 0, meaning all results. The deployment theme default accepts system, light, or dark.
Feature flags for server operations and accepted values are checked on Workbench requests as well as reflected in the controls. A request that sets a disabled option to a value other than its default is rejected with 403 Forbidden; the default itself is accepted. The defaults are the default-queryLn, default-query-timeout and default-infer init parameters of the Workbench servlet (see below) for query-language, query-timeout and query-inferred-statements, and query.download.default-limit for result-download-limit. Some flags describe only user-interface actions that share an enabled operation: query-rerun hides and disables the Explain again entry point while query-explain is still allowed, and editor-fullscreen controls the YASQE fullscreen toggle and F11 shortcut. These are presentation controls, not authorization boundaries; use RDF4J’s security configuration to restrict access to server operations or data.
Workbench queries have a default timeout of 60 seconds, set by the default-query-timeout init parameter of the
Workbench servlet (in WEB-INF/web.xml of the WAR, and in the registration of the Spring Boot runner). Earlier releases
defaulted to 0, which means no limit. Users can change the timeout for their queries in the Query settings; when the
query-timeout feature is disabled, the default applies to every query. To restore unlimited queries by default, set
default-query-timeout to 0 in WEB-INF/web.xml.
The timeout can also be set in workbench.properties with query.default-timeout, a non-negative number of seconds
(0 means no limit). The key is not part of the packaged defaults: when it is absent the default-query-timeout init
parameter keeps applying, and when it is present it takes precedence over that init parameter, for every page that uses
the default. A negative or non-numeric value is a configuration error.
query.default-timeout=120
A query that runs longer than its timeout is reported as timed out (“Query timed out after 1 second”), also when the Workbench stopped waiting for the RDF4J Server’s answer just before the server reported the timeout itself; rows that were already received are kept.
By default the “New repository” page offers every built-in repository type and Federation. A distribution can restrict
and reorder that list, and add its own types, with create.templates in workbench.properties: a list of repository
template types separated by commas and/or whitespace. The key is not part of the packaged defaults; when it is absent or
blank nothing changes.
create.templates=native, memory, federate, acme-graph
When the key is set, the page offers exactly the listed types, in the order listed (they are not sorted), labelled with
the label of each template. federate is a pseudo-type that stands for the Federation option; leave it out to remove
Federation. The list may also name built-in templates that are normally hidden, such as memory-rdfs-legacy, and your
own templates: a template is a Turtle file with the Workbench template annotations of the built-in ones, placed in
WEB-INF/classes/org/eclipse/rdf4j/repository/config/<type>.ttl (or on the class path under the same package), and
named in the list by its file name without .ttl.
Types outside the list are refused: requesting the form of an unlisted type answers 404 Not Found, and posting one
answers 400 Bad Request without creating a repository. The list is checked when the policy is loaded: an entry that
contains characters other than letters, digits, ., _ and -, a type listed twice, or a type whose template cannot be
loaded makes the whole policy invalid, so every Workbench page answers 503 Service Unavailable as described above.
The Query and Update editors know the namespaces of the repository. They complete a prefix after PREFIX, and
typing a prefixed name such as skos:Concept adds the missing PREFIX skos: <…> line at the top of the query.
Insert prefixes (under Query settings) adds a line for every repository namespace the query does not declare yet.
For a prefix that the repository does not define, the editors fall back on a second list of prefixes. Typing a prefixed
name from this list adds its PREFIX line, as for a repository namespace. Insert prefixes never adds the fallback
list. The Workbench ships with an empty fallback list; a deployment sets its own with namespaces.fallback.
Two keys of workbench.properties change this. Neither is part of the packaged defaults. Each takes prefix:namespace
entries separated by commas and/or whitespace. A namespace may be written in angle brackets, which it needs when it
contains a comma. A prefix may be empty (:http://example.org/, the default namespace).
# Namespaces that every repository has, as far as the Workbench is concerned.
namespaces=dcat:http://www.w3.org/ns/dcat# acme:<https://acme.example/vocab#>
# The prefixes the editors fall back on; an empty value turns the fallback off.
namespaces.fallback=schema:https://schema.org/ foaf:http://xmlns.com/foaf/0.1/
namespaces: pages treat these namespaces as if every repository had stored them. This covers the editors and
Insert prefixes, and the prefixed names in the result tables, Explore, the Remove preview and the other pages
that show the repository’s prefixes. A prefix that a repository stores keeps the repository’s namespace. The
Namespaces page lists, and changes, only the namespaces the repository stores.namespaces.fallback: the fallback list. It replaces the whole bundled list (empty in this release) rather than
adding to it. An empty value turns the fallback off.An entry without a colon, an invalid prefix, a namespace that is not an absolute IRI, or a prefix listed twice makes
the whole policy invalid. Every Workbench page then answers 503 Service Unavailable, as described above. The editors
load the fallback list once per page from <workbench>/fallback-namespaces. Browsers check it again on every page
load, so a changed list reaches the editors as soon as the Workbench has restarted.
RDF4J Server can optionally be instrumented with OpenTelemetry tracing, recording one span per SPARQL query/update evaluated against a repository. This is entirely opt-in: with no configuration, RDF4J Server behaves exactly as before, with zero overhead. For general background on RDF4J’s OpenTelemetry support (the underlying module, its configuration options, and programmatic use outside of Server/Workbench), see Observability using OpenTelemetry.
Server-side, tracing every repository served by RDF4J Server’s repository manager is gated by a single system property:
org.eclipse.rdf4j.opentelemetry.enabled=true
Disabled by default. This can be set like any other RDF4J system property, e.g. via JAVA_OPTS/CATALINA_OPTS (see “Application directory configuration” above), or, in the Docker images, via RDF4J_OPTS as shown below. The remaining tracing behaviour (whether query text is captured, truncation length, db.system.name, …) is configured via the system properties listed in Observability using OpenTelemetry.
The docker/ Dockerfiles for both Tomcat and Jetty bundle the OpenTelemetry Java agent and can activate it purely through environment variables - no image rebuild required.
| Variable | Effect |
|---|---|
OTEL_EXPORTER_OTLP_ENDPOINT | Presence of this variable is what switches tracing on. Set it to the OTLP endpoint of your collector/backend (e.g. http://otel-collector:4318). If unset, the agent is never attached and there is no overhead. |
OTEL_SERVICE_NAME | The service.name reported for spans. Defaults to rdf4j. |
RDF4J_OPTS | Extra JVM options (typically further -D system properties, see above) appended on top of the image’s own defaults, without having to repeat them. |
Example docker-compose.yml snippet:
services:
  rdf4j:
    environment:
      - OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318
      - OTEL_SERVICE_NAME=rdf4j
      - RDF4J_OPTS=-Dorg.eclipse.rdf4j.opentelemetry.enabled=true -Dorg.eclipse.rdf4j.opentelemetry.captureQueryText=true
      - OTEL_INSTRUMENTATION_SERVLET_ENABLED=false
      - OTEL_INSTRUMENTATION_LOGBACK_APPENDER_ENABLED=false
      - OTEL_INSTRUMENTATION_LOGBACK_MDC_ENABLED=false
      - OTEL_LOGS_EXPORTER=none
Required for RDF4J Server/Workbench. Any other OpenTelemetry Java agent behaviour (individual instrumentation modules, sampling, …) is configured the standard OpenTelemetry way, via further OTEL_* environment variables that the agent reads directly - but the four settings below are not optional tuning, they work around two agent/instrumentation bugs that otherwise break RDF4J Server when the agent is attached. Set all four:
OTEL_INSTRUMENTATION_SERVLET_ENABLED=false
OTEL_INSTRUMENTATION_LOGBACK_APPENDER_ENABLED=false
OTEL_INSTRUMENTATION_LOGBACK_MDC_ENABLED=false
OTEL_LOGS_EXPORTER=none
OTEL_INSTRUMENTATION_SERVLET_ENABLED=false - without this, RDF4J Server responses can come back empty/corrupted. The generic Servlet auto-instrumentation interferes with RDF4J Server’s manually-streamed, chunked binary query result responses - observed as an HTTP 200 response with the correct headers but a zero-byte body (e.g. on GET /repositories). Repository/query spans (the actual purpose of this module) are unaffected by disabling this, since those come from RDF4J’s own instrumentation, not the generic Servlet instrumentation.OTEL_LOGS_EXPORTER=none, OTEL_INSTRUMENTATION_LOGBACK_APPENDER_ENABLED=false, OTEL_INSTRUMENTATION_LOGBACK_MDC_ENABLED=false - without these, RDF4J Server/Workbench can crash with a NoSuchFieldError while logging. RDF4J Server and Workbench are deployed as two separate WARs, each bundling their own copy of logback-classic; the agent’s logback instrumentation injects a virtual field onto the shared LoggingEvent class, which is not consistent across the two WARs’ isolated classloaders and throws at runtime. RDF4J does not emit any OpenTelemetry log records, so disabling all three has no downside.Each repository in RDF4J Server stores both its configuration and the actual persisted data in the application dir. The location is [RDF4J_DATA]/server/repositories/[REPOSITORY_ID]. The configuration is stored as a file config.ttl in that directory. The other files in this directory represent stored data, indexes and other files that the database needs to persist its data (in other words: best don’t touch).
The easiest way to create and manage repositories on an RDF4J Server to use the RDF4J Console or RDF4J Workbench. Both offer commands to quickly create a new repository and guide you through the various configuration options.
However, you can also directly edit the config.ttl of your repository to change its configuration. For example, you can use this to change the repository name as it is shown in the Workbench, or perhaps to change configuration parameters, or change the repository type. However, proceed with caution: if you make a mistake, your repository may become unreadable until after you’ve rectified the mistake. Also note that if you change the actual store type (e.g. switching from a memory store to a native store), it won’t migrate your existing data to the new store configuration!
The different types of repository are:
More information can be found in the Repository configuration and templates section of the documentation.
Both RDF4J Server and RDF4J Workbench use the Logback logging framework. In its default configuration, all RDF4J Server log messages are sent to the log file [RDF4J_DATA]/Server/logs/main.log (and log messages for the Workbench to the same file in [RDF4J_DATA]/Workbench ).
The default log level is INFO, indicating that only important status messages, warnings and errors are logged. The log level and -behaviour can be adjusted by modifying the [RDF4J_DATA]/Server/conf/logback.xml file. This file will be generated when the server is first run. Please consult the logback manual for configuration instructions.
The built-in /system/logging/overview.view page is disabled by default and returns 403 Forbidden. Server logs can include request URLs, query parameters, error details, and stack traces. To enable the page, start the Server JVM with -Dorg.eclipse.rdf4j.server.logging.ui.enabled=true. For the packaged Spring Boot distribution, add this option through RDF4J_JAVA_OPTS; for a standalone WAR, add it to the servlet container’s JVM options. This setting only makes the page available. Protect /system/logging/* with servlet-container authentication and authorization or an authenticating reverse proxy before enabling it. For the packaged Boot server, protect both /system/logging/* and /rdf4j-server/system/logging/* when using a reverse proxy. The page must not be exposed anonymously on a publicly reachable listener.
Downstream distributions can add or replace Spring beans in RDF4J Server without modifying the WAR’s own configuration files. At the end of its rdf4j-http-server-servlet.xml, the server imports every Spring XML file that it finds on the classpath at META-INF/rdf4j-server/*.xml:
META-INF/rdf4j-server/<name>.xml inside a jar in WEB-INF/lib, or directly under WEB-INF/classes/META-INF/rdf4j-server/.rdf4j-server-boot), put the jar (or directory) containing the file on the application classpath.Extension files are loaded after all stock bean definitions. A bean with the same id as a stock bean replaces it, so you can, for example, replace the rdf4jRepositoryManager bean that the server’s controllers reference by name. The stock URL handler mappings use orders 0 to 3; give your own mappings an order that does not conflict with these. The commonAppConfig bean is available to extensions (for instance to look up the data directory). The order in which several extension files are loaded is not specified, so do not make one extension file depend on another. When packaging extensions in a jar, make sure the jar has directory entries (jars built by Maven do), as the classpath lookup relies on them.
The following example replaces the repository manager with a custom FactoryBean and adds a URL mapping to a custom controller:
<?xml version="1.0" encoding="UTF-8"?>
<beans xmlns="http://www.springframework.org/schema/beans"
	xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
	xsi:schemaLocation="http://www.springframework.org/schema/beans http://www.springframework.org/schema/beans/spring-beans.xsd">

	<!-- Replaces the stock repository manager. The class must produce a RepositoryManager. -->
	<bean id="rdf4jRepositoryManager" class="com.example.CustomRepositoryManagerFactoryBean">
		<constructor-arg>
			<bean factory-bean="commonAppConfig" factory-method="getDataDir" />
		</constructor-arg>
	</bean>

	<bean id="exampleController" class="com.example.ExampleController" />

	<!-- Adds a new endpoint; the stock mappings use orders 0-3. -->
	<bean id="exampleHandlerMapping" class="org.springframework.web.servlet.handler.SimpleUrlHandlerMapping">
		<property name="order" value="10" />
		<property name="urlMap">
			<map>
				<entry key="/example" value-ref="exampleController" />
			</map>
		</property>
	</bean>
</beans>
It is possible to set up your RDF4J Server to authenticate named users and restrict their permissions. RDF4J Server is a servlet-based Web application deployed to any standard servlet container (for the remainder of this section it is assumed that Tomcat is being used).
The RDF4J Server exposes its functionality using a REST API that is an extension of the SPARQL protocol for RDF. This protocol defines exactly what operations can be achieved using specific URL patterns and HTTP methods (GET, POST, PUT, DELETE). Each combination of URL pattern and HTTP method can be associated with a set of user roles, thus giving very fine-grained control.
In general, read operations are effected using GET and write operations using PUT, POST and DELETE. The exception to this is that POST is allowed for SPARQL queries. This is for practical reasons, because some HTTP servers have limits on the length of the parameter values for GET requests.
RDF4J Server checks Origin, Referer, and Sec-Fetch-Site on state-changing requests to /repositories and its descendants. It rejects a browser request from another origin unless the request carries X-RDF4J-Request: true. That non-simple header makes the browser ask for CORS permission before sending the request; the deployment must explicitly permit that origin and header. API clients that do not send browser origin metadata continue to work without the header. These request checks do not replace authentication or repository permissions. A reverse proxy must pass the public scheme, host, and port to the servlet container so same-origin requests compare correctly.
RDF4J Workbench requires a session-bound request token on state-changing requests to /repositories and its descendants. Its pages add the token automatically to forms and same-origin requests. A custom client posting to Workbench must first load a Workbench page in the same session, then send the rdf4j-workbench-csrf cookie value as the X-RDF4J-CSRF-Token header or _csrf form field. Cross-origin browser requests are rejected even if they include a token. Clients that use the RDF4J protocol should call Server rather than Workbench directly.
The association between operations and security roles is specified using security constraints in RDF4J Server’s deployment descriptor - a file called web.xml that can be found in the .../webapps/rdf4j-server/WEB-INF directory. web.xml becomes available immediately after the installation without any security roles defined.
Warning: When redeployed, the web.xml file gets overwritten with the default version. Therefore, if you change it, make sure you create a backup. In particular, do not edit web.xml while Tomcat is running.
The deployment descriptor defines:
To enable authentication, add the following XML element to web.xml inside the <web-app> element:
    <login-config>
        <auth-method>BASIC</auth-method>
        <realm-name>rdf4j</realm-name>
    </login-config>
Security constraints associate operations (URL pattern plus HTTP method) with security roles. Both security constraints and security roles are nested in the <web-app> element.
A security constraint minimally consists of a collection of web resources (defined in terms of URL patterns and HTTP methods) and an authorisation constraint (the role name that has access to the resource collection). Some example security constraints are shown below:
<security-constraint>
    <web-resource-collection>
        <web-resource-name>SPARQL query access to the 'test' repository</web-resource-name>
        <url-pattern>/repositories/test</url-pattern>
        <http-method>GET</http-method>
        <http-method>POST</http-method>
    </web-resource-collection>
    <auth-constraint>
        <role-name>viewer</role-name>
        <role-name>editor</role-name>
    </auth-constraint>
</security-constraint>

<security-constraint>
    <web-resource-collection>
        <web-resource-name>
        Read access to 'test' repository's namespaces, size, contexts, etc
        </web-resource-name>
        <url-pattern>/repositories/test/*</url-pattern>
        <http-method>GET</http-method>
</web-resource-collection>
    <auth-constraint>
        <role-name>viewer</role-name>
        <role-name>editor</role-name>
    </auth-constraint>
</security-constraint>

<security-constraint>
    <web-resource-collection>
        <web-resource-name>Write access</web-resource-name>
        <url-pattern>/repositories/test/*</url-pattern>
        <http-method>POST</http-method>
        <http-method>PUT</http-method>
        <http-method>DELETE</http-method>
    </web-resource-collection>
    <auth-constraint>
        <role-name>editor</role-name>
    </auth-constraint>
</security-constraint>
The ability to create and delete repositories requires access to the SYSTEM repository. An administrator security constraint for this looks like the following:
<security-constraint>
    <web-resource-collection>
        <web-resource-name>Administrator access to SYSTEM</web-resource-name>
        <url-pattern>/repositories/SYSTEM/</url-pattern>
        <url-pattern>/repositories/SYSTEM/*/</url-pattern>
        <http-method>GET</http-method>
        <http-method>POST</http-method>
        <http-method>PUT</http-method>
        <http-method>DELETE</http-method>
    </web-resource-collection>
    <auth-constraint>
        <role-name>administrator</role-name>
    </auth-constraint>
</security-constraint>
Also nested inside the <web-app> element are definitions of security roles. The format is shown by the example:
<security-role>
    <description>
        Read only access to repository data
    </description>
    <role-name>viewer</role-name>
</security-role>

<security-role>
    <description>
        Read/write access to repository data
    </description>
    <role-name>editor</role-name>
</security-role>

<security-role>
    <description>
        Full control over the repository, as well as creating/deleting repositories
    </description>
    <role-name>administrator</role-name>
</security-role>
Server and Workbench do not expose JVM system-property administration. Configure LMDB properties through the JVM startup configuration and use repository configuration to enable the native query engine.
GET /repositories/{id}/lmdb/strategies lists native execution strategies for the selected repository, using its normal
repository routing and access rules. It returns an empty list when native execution is unavailable or disabled.
Workbench shows the per-query strategy selector only after the selected repository advertises available strategies.
The empty choice leaves strategy selection to the engine. A forced strategy must still be eligible for the query.
Tomcat has a number of ways to manage user accounts. The different techniques are called ‘realms’ and the default one is called ‘UserDatabaseRealm’. This is the simplest one to manage, but also the least secure, because usernames and passwords are stored in plain text.
For the default security realm, usernames and passwords are stored in the file tomcat-users.xml in the Tomcat configuration directory, usually /etc/tomcat/tomcat-users.xml on Linux systems. To add user accounts, add <user> elements inside the <tomcat-users> element, for example:
<user username="adam" password="secret" roles="viewer" />
<user username="eve" password="password" roles="viewer,editor,administrator" />
To use a remote repository where authentication has been enabled, it is necessary to provide the username and password to the RDF4J API. Remote repositories are usually accessed via the RemoteRepositoryManager
class. Tell the repository manager what the security credentials are using the following method:
void setUsernameAndPassword(String username, String password)
Alternatively, they can be passed in the factory method:
static RemoteRepositoryManager getInstance(String serverURL, String username, String password)
This chapter describes the RDF4J Workbench, a web application for interacting with RDF4J and/or other SPARQL endpoints.
This chapter will refer to URLs on a local server served from port 8080, which is possibly the most common “out-of-the-box” configuration. That is, Workbench URLs will start with http://localhost:8080/.
To start using Workbench for the first time, point your browser to http://localhost:8080/rdf4j-workbench. Your browser will be automatically redirected to http://localhost:8080/rdf4j-workbench/repositories/NONE/repositories. This page will display all repositories in the default server, as indicated by the “default-server” property in WEB-INF/web.xml. Normally this is set to /rdf4j-server. That is, the default server for Workbench is usually the RDF4J Server instance at the path /rdf4j-server on the same web server. To view information about the RDF4J Server instance, click on “RDF4J Server” at the top of the side menu.
A “current selection” section sits at the top right in the Workbench, informing you of the URL of the server you are using, the repository you are currently using, and the user name used when accessing the server. Each of these items can be changed by clicking the “change” link immediately to the right of them. Since the Workbench is generally used for prototyping and exploration, “user” is commonly set to “none”. In this case, the Workbench is connecting to the RDF4J Server without authenticating, and below we refer to the user in this mode as the anonymous user.
There are two ways to reach the “Change Server” page, which allows you to enter a URL for the server and, optionally, user credentials:
A full URL is expected in the “Change Server” field. You may enter a file:/// URL to access a local repository on the Workbench server, but need to be sure that the Workbench server process has permission to access the given folder.
User names and passwords may contain any characters: the Workbench stores the credentials UTF-8 encoded (base64 of the UTF-8 bytes of user:password in the server-user-password cookie) and sends them to the RDF4J Server UTF-8 encoded.
For security, Workbench does not allow users to switch to arbitrary servers by default. A server URL entered on the “Change Server” page must start with one of the accepted server prefixes before Workbench will connect to it. The default accepted prefix is /rdf4j-server, which allows the RDF4J Server deployed next to Workbench and rejects remote http://..., https://..., and file:///... targets unless an administrator explicitly allows them.
Administrators can configure the allow-list as a whitespace-separated list of concrete prefixes. The JVM system property org.eclipse.rdf4j.workbench.accepted-server-prefixes has highest precedence and overrides the Workbench servlet init-param accepted-server-prefixes in WEB-INF/web.xml. If neither value is set to a non-blank value, Workbench uses /rdf4j-server.
For example, when starting rdf4j-server-boot or a servlet container, allow the local server and two remote RDF4J Server deployments like this:
-Dorg.eclipse.rdf4j.workbench.accepted-server-prefixes="/rdf4j-server https://rdf4j.example.org/rdf4j-server https://staging.example.net/rdf4j-server"
For WAR deployments, you can instead edit the Workbench servlet init-param:
<init-param>
  <param-name>accepted-server-prefixes</param-name>
  <param-value>/rdf4j-server https://rdf4j.example.org/rdf4j-server</param-value>
</init-param>
Use concrete host/path prefixes. Prefixes are plain prefix matches with a path, query, or fragment boundary; they are not regular expressions. Scheme-only http:, https:, and file: entries are ignored. Broad http:// or https:// prefixes are technically possible but not recommended because they allow Workbench users to make server-side connections to arbitrary HTTP(S) hosts. To allow a local file repository, configure a specific file:///... directory prefix and make sure the Workbench process can read that directory.
Workbench stores user name and password credentials in plain-text cookies in the browser. You will need to configure your Workbench server for HTTPS to properly protect these credentials. See the Tomcat 8.5 or Tomcat 9 SSL/TLS documentation for more information.
There are two ways to change the current repsository:
You will be presented with a table listing of all the repositories available on the current server, with the following columns:
“Location” is the URL of the repository, useful for accessing it via the RDF4J REST API. “Id” is presented as a clickable hyperlink that will open that repository in the Workbench, bringing the user to a summary page for the repository.
Click on “New repository” in the sidebar menu. This brings up the “New Repository” page. You are presented with a simple form that provides a “Type:” selector with several repository types:
Deployments can restrict this list, reorder it and add their own types with the create.templates policy key (see Repository types offered when creating a repository).
The “ID:” and “Title:” fields are optional in this form. Clicking “Next” brings up a form with more fields specific to the repository type selected. On that form, it will be necessary to enter something in the “ID:” field before the “Create” button may be clicked. If creation is successful, the new repository is also opened and its “Summary” page is presented.
A repository ID is part of the repository’s URLs (and, on a local server, the name of its data directory), so the Workbench only creates repositories whose ID consists of the letters a–z and A–Z, digits, -, _, . and @, and is not made of dots only (. and .. are not valid IDs). Other IDs are refused with a message saying so.
Data may be added to or removed from current repository using any of the sidebar menu items under “Modify”. After all successful operations, the user is presented with the repository “Summary” page.
The “Add” page allows you to specify a URL with RDF data, a local file on your client system, or to enter serialized RDF data into its text area for loading into the present repository. It is also possible to specify the Base URI and a Context for the triples. Think of the Context as a 4th element of each RDF statement, specifying a graph within the repository. You may specify one of eight serialization formats, or select “auto-detect” to let the server do a best guess at the format.
When the data is to be read from a URL that cannot be read (for example because it answers 404 Not Found or its server cannot be reached), the Add page says so (“Could not read
Local files (and URLs that serve compressed bytes) may be gzip-compressed for faster transfer, for example data.ttl.gz or data.rdf.gzip. Workbench decompresses the stream automatically before parsing. With auto-detect, the RDF format is taken from the name after the compression suffix (ttl in data.ttl.gz). Gzip is always available; deflate, zstd, and brotli are used when the matching library is on the classpath. Zip archives (.zip with multiple entries) are not unpacked here.
The “Remove Statements” page presents you with a form where you may enter values for subject, predicate, object or context. Clicking on “Remove” then removes all statements from the repository which match the given values. Leaving an item blank means that any value will match. If all values are left blank, clicking “Remove” will not do anything except present a warning message.
The “Clear Repository” page is powerful. Leaving the lone “Context:” field blank and clicking “Clear Context(s)” will remove all statements from all graphs in the repository. It is also possible to enter a resource value corresponding to a context that exists in the repository, and the statements for that graph only will be removed.
The “Execute SPARQL Update on Repository” page gives a text area where you enter a SPARQL 1.1 Update command. SPARQL Update is an extension to the SPARQL query language that provides full CRUD (Create Read Update Delete) capabilities. For more information see the W3C Recommendation for SPARQL 1.1 Update. Clicking “Execute” executes the specified SPARQL Update operation. The browser keeps what you type as a draft for each repository (and server), so an update written for one repository is never waiting, ready to run, on another repository’s page.
When a repository with SHACL validation rejects a change made with Add, Remove, Clear or SPARQL Update, the Workbench lists the violations, one per line, with the focus node, the path, the offending value and what the constraint expected (or the shape’s sh:message), for example - ex:alice, ex:age: value "abc": expected datatype xsd:integer. Long reports list their first 20 violations.
Click on “Summary” on the sidebar menu. A simple summary is displayed with the repository’s id, description, URL for remote access and the associated server’s URL for remote access. Many operations when repositories are created and updated display this page afterwards.
Namespace-prefix pairings can be defined within a repository, so that URIs can be displayed in shorthand form as a qualified name. To edit them, click on “Namespaces” on the sidebar menu. A page is displayed with a table of all presently defined pairs. Existing namespaces may be edited by selecting them in the drop-down list, which populates the text fields. The text fields may then be edited, and the “Update” button will make the change on the repository. The “Delete” button will remove whichever pair has been selected.
A change never silently replaces another binding: renaming a prefix onto one that is already defined is refused, and adding a prefix that is already bound to a different namespace replaces that namespace only once you confirm it.
“Context” is the RDF4J construct for implementing RDF Named Graphs, which allow a repository to group data into separately addressable graphs. The Explore page always displays the context (always a URI or blank node) with each triple, the combination of which is often referred to as a quad.
To view all the contexts for the present repository, click on “Contexts” on the sidebar menu. Each context is clickable, bringing you to the “Explore” page for that context value.
Click on “Types” on the sidebar menu. A list of types is displayed. These types are the resulting output from this SPARQL query:
SELECT DISTINCT ?type WHERE { ?subj a ?type }
Click on “Explore” in the sidebar menu. You are presented with an “Explore” page. Type a resource value into the empty “Resource” field, and hit Enter. You will be presented with a table listing all triples where your given resource is a part of the statement, or is the context (graph) name. Currently allowable resource values are:
<http://www.w3.org/1999/02/22-rdf-syntax-ns#type>“dog”@en or “hund”@de or “1”^^xsd:integer or “9.99”^^<http://www.w3.org/2001/XMLSchema#decimal>Data types expressed with qnames also need to have their namespace defined in the repository.
By using the “Results per page” setting and the “Previous …” and “Next …” buttons, you may page through a long set of results, or display all of the results at once. There is also a “Show data types & language tags” checkbox which, when un-checked, allows a less verbose table view. Explore remembers what you explored in each repository, with its page and “Results per page”, until you close the browser tab: open it again from the sidebar menu (or from another repository and back) and it shows that resource again. Explore an empty “Resource” field to start afresh.
Click on “Graph” in the sidebar menu to explore the repository as an interactive graph. The graph starts empty: load the first 100 statements, find a resource with the search field in the top-left corner of the canvas (it lists the loaded nodes as you type, and its last choice searches the repository’s labels and adds the matching resources), or run a query in the query editor. Queries may be CONSTRUCT or DESCRIBE queries, or SELECT queries whose result columns name a ?source, a ?predicate and a ?target (or ?s, ?p, ?o). The other Workbench pages offer “Add to graph” as well: on a resource in Explore (the resource and its neighbours), on any IRI in a result table, on the results of a query on the Query page, and on the rows of the Types (instances of the type) and Graphs (statements of the named graph) pages; what is added appears on the Graph page of the same repository the next time it opens, or straight away in a Graph page open in another tab. The graph, its layout, groups and selection are kept in the browser (per repository) and come back when the page is opened again; “Clear graph” empties it, and Undo brings it back.
Resources are drawn as nodes, coloured by RDF type, and the links between them as edges. Click a node to see its details (types, literal values and links, each link leading to the linked node); double-click it, or use “Expand” in the details, to load its neighbours. A number such as “+12” on a node says how many of its links are not loaded yet; click it, or expand the node again, to load the next ones. Literal values and rdf:type links are shown in the details rather than as nodes; “Values” draws them as nodes too. Click a link (or next to it) to see its statement: what the predicate means (its description, domain and range, how many statements use it), and a card for every resource that says something about the statement: RDF 1.2 reifiers (<< s p o >> and {| … |} annotations), classic rdf:Statement reifications, and statements that refer to the triple term <<( s p o )>>; each card can be added to the graph. The details of a node offer the same statement card for each of its values and links (“Statement: …”), which also works from the keyboard. A reifier, or a resource that refers to a triple term, is connected to the statement it is about by a dashed line to the middle of the statement’s edge. Right-click or long-press a node for more actions, such as expanding a single relation or selecting neighbours; the type names under the graph select the nodes of a type. “Filters” narrows the selection by type and by the values of the nodes’ properties, including values the repository has that are not loaded (they load in the background, are kept in the browser for an hour and load again after any change made through the Workbench): the counts always say how many nodes a choice would select, choices that would select nothing are left out, numbers and dates are filtered by a from–to range, and the active filters are listed as chips at the top of the panel. Open the query editor (“Query editor”) to change the query, or to hand it over to the Query page (“Open on the Query page”). The view menu beside “Query editor” (it shows the name of the current view, “Graph” at first) shows the same data as a triple table, cards, an adjacency matrix, a timeline, a map (of WKT points, and of geo:lat/geo:long or schema:latitude/schema:longitude values, also on a schema:geo node) or value charts (one numeric property at a time); while nodes are selected, these views show only the statements of the selection, and the triple table shows 500 rows at a time. “Tools” downloads the loaded statements as Turtle and the drawn graph as an SVG or PNG image; on a narrow screen it also holds undo, redo, “Values”, “Labels” and full screen, so that the toolbar stays one row. The “?” button near the end of the toolbar lists every mouse, touch and keyboard control.
The page is built for large graphs: 50,000 nodes and 200,000 links load in a few seconds and move smoothly. From 500 drawn nodes it switches to a WebGL renderer that shows labels when zoomed in or for the selected node, the layout is computed in the background (“Arranging…” is shown meanwhile), and the stored copy takes about 12 MB of browser storage.
All queries are sent through the Workbench to the repository (/repositories/<id>/graph), so the credentials of the Workbench session apply and the browser never contacts the RDF4J Server directly. The page honours the query-execution feature of the Workbench policy (it answers HTTP 403 when disabled) and the graph-max-query-length init parameter of the Workbench servlet (default 150000 characters, HTTP 413 beyond it). It is hidden like any other built-in page with menu.item.graph.visible=false or by leaving graph out of menu.items.
Clicking on “Query” on the sidebar menu brings you to Workbench’s querying interface. Here, you may enter queries in the SPARQL language, save them for future access, and execute them against your repository.
If you have executed queries previously, the query text area will show the most recently executed query. If not, it will be pre-populated with a prefix header containing all the defined namespaces for the repository. The “Clear” button below the text area gives you the option to restore this pre-populated state for the currently selected query language.
The two other action buttons are “Save Query” and “Execute”:
For an ordinary, non-transactional query, the Query page shows a Cancel action while the query runs; Cancel stops the query on the server and keeps the results that have already arrived. Running the query again, editing a query that is being explained, or leaving the page also cancels the running query or explanation. The streamed result ends with a completion or failure record, so the page knows when the query has finished; a result download cannot signal its completion to the page.
Cancellation identifiers are scoped to a repository. Clients do not need to supply an identifier for automatic cancellation; Server generates and registers one for the request. In a deployment with multiple RDF4J Server instances, a cancellation request that reaches an instance that does not own the query can return 404, while cancellation of an active query on the owning instance returns 204. Workbench retries failed cancellation requests a bounded number of times. When an HTTP-backed repository forwards cancellation to another RDF4J Server, a downstream failure is reported as 502 so the request can be retried instead of being acknowledged as successful.
For supported result formats, RDF4J Server and Workbench can flush one ASCII space approximately every second while evaluation is waiting for the first result. The probe uses the negotiated writer’s response stream and stops before the first byte written by the serializer. XML declarations are omitted before probing when the selected XML writer supports that setting. The supported formats are SPARQL Results JSON and XML, JSON-LD, NDJSON-LD, RDF/JSON, Turtle, N3, TriG, N-Triples, N-Quads, RDF/XML, and TriX; RDF/XML and TriX require the actual XML writer to support omitting its processing instruction. See the SPARQL Results JSON, SPARQL Results XML, JSON-LD 1.1, and RDF 1.1 Turtle specifications for the relevant grammars.
Heartbeats are excluded for binary formats, CSV, TSV, XLSX, plain boolean responses, unknown formats, invalid requests, and HEAD responses. Proxy and TCP buffering can delay when a disconnected client is detected. The first heartbeat flush commits the response status and headers even when the serializer buffers ordinary bytes. Before that commitment, an evaluation or validation failure can use the normal HTTP error response. A failed response write triggers cancellation. After commitment, a query or evaluation failure terminates or invalidates the response body but does not necessarily invoke cancellation; the status may remain 200, and the client must not treat an incomplete body as a successful empty result.
This cancellation and disconnect handling does not apply to transaction-bound queries. A transaction connection may own pending updates and other work, so closing it to stop one result could invalidate the entire transaction.
Clicking “Saved queries” on the sidebar menu brings you to the Workbench’s interface for working with previously saved queries. All saved queries accessible to the current user are listed in alphabetical order by
The query name is displayed as a clickable link that will execute the query, followed by 3 buttons:
Show: Toggles the display of the query metadata and query text. When the “Save Queries” page loads, this information is not showing to conserve screen real estate.Edit: Brings you to the query entry page, pre-populated with the query text.Delete...: Deletes the saved query, with a confirmation dialog provided for safety. Users may only delete their own queries or queries that were saved anonymously.The query metadata fields, aside from query name and user, are:
Note that it is only possible to save queries as the present user. If you edit another user’s query and save it with the same query name, a new saved query will be created associated with your user name.
The “Export” link on the sidebar menu is convenient for bringing up a paged view of all quads in your triple store. As with other result views, resources are displayed as clickable links that bring you to that resource’s “Explore” page. In addition, it is possible to select from a number of serialization formats to download the entire contents of the triple store in:
NOTE: new in RDF4J 3.0
Workbench supports two SHACL wrapped stores.
Shapes need to be loaded into the following context:
<http://rdf4j.org/schema/rdf4j#SHACLShapeGraph>
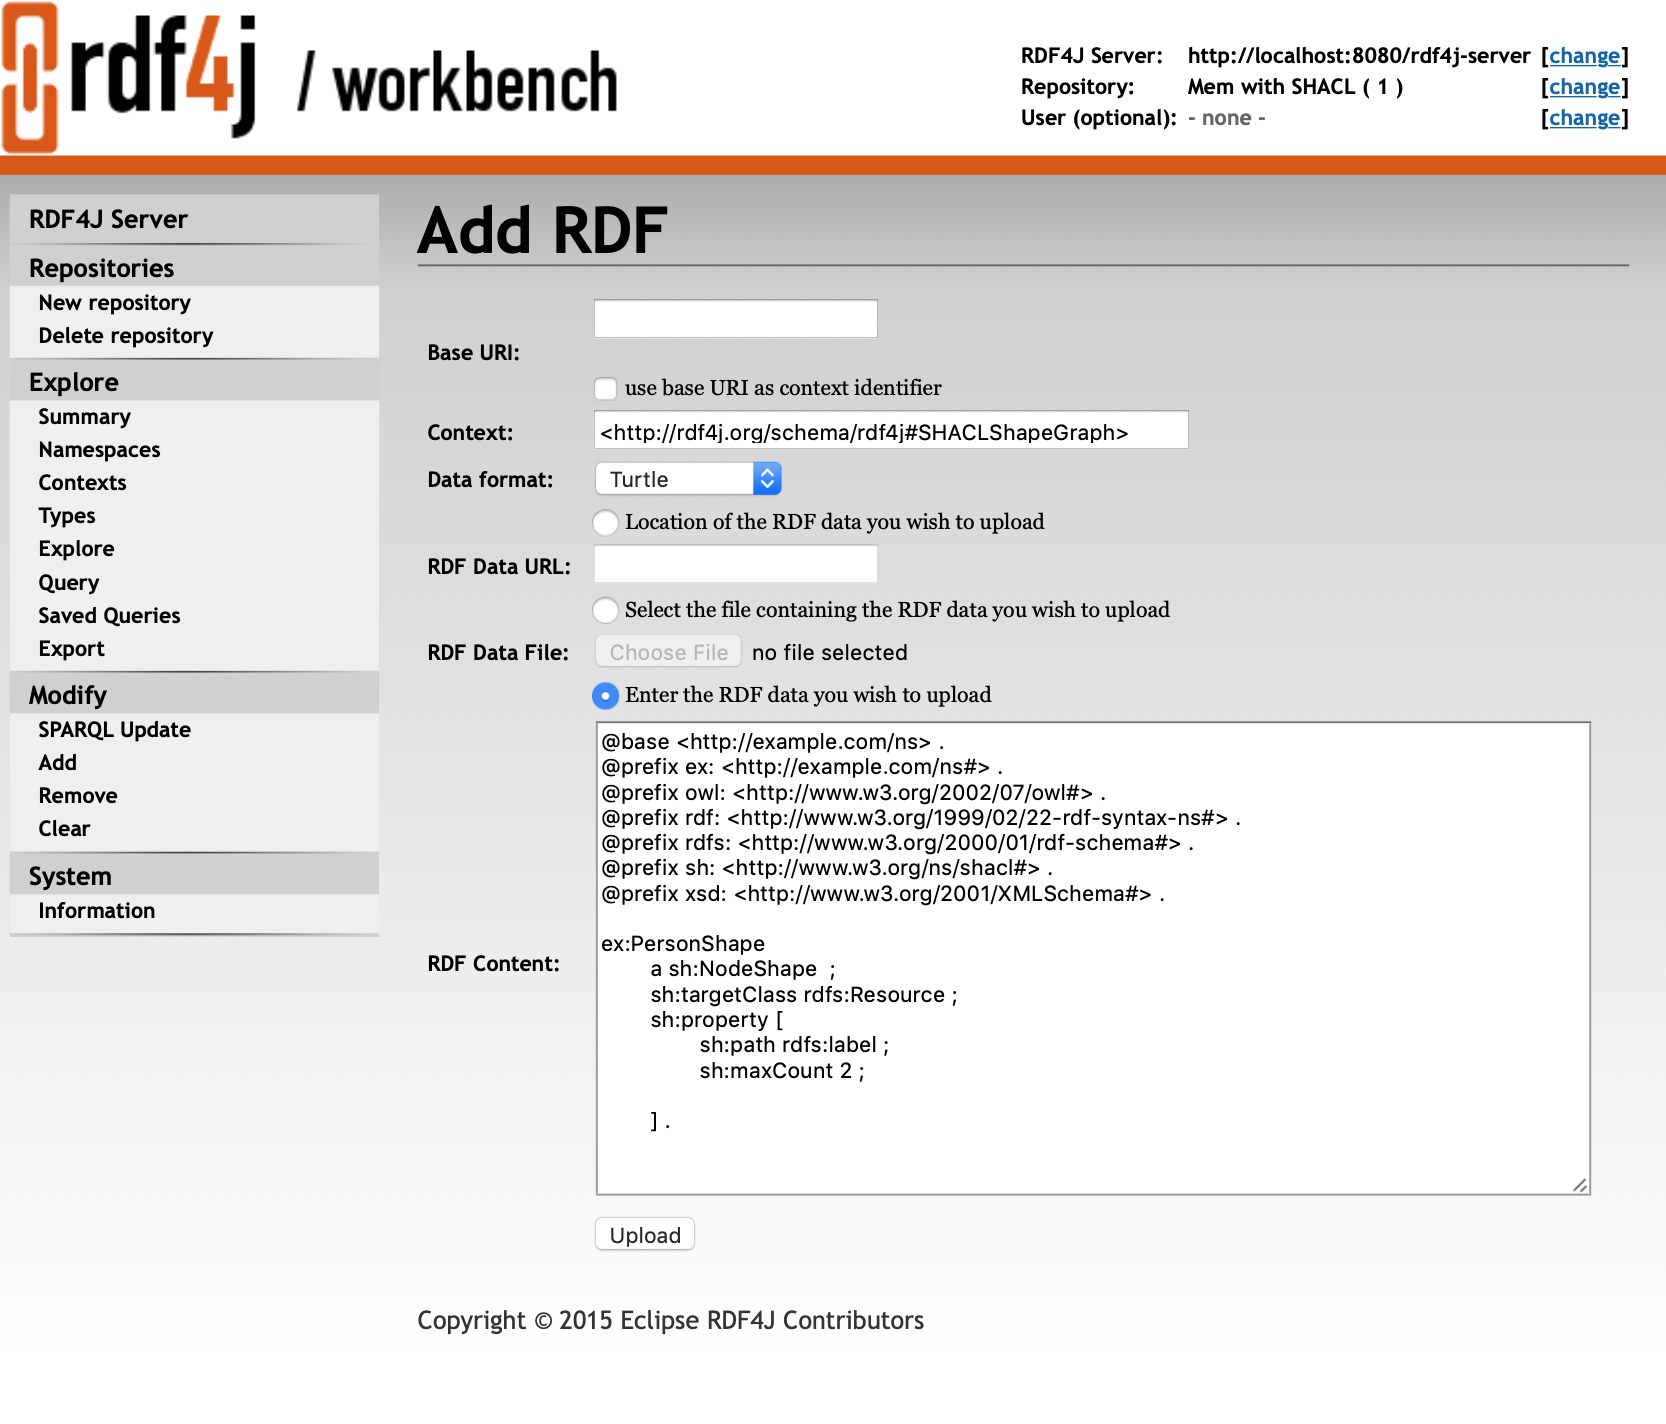
This context is a hidden context that is only available through the following commands:
To update your shapes you should first clear the shapes context and then add your shapes again.
There is no functionality in the user interface to retrieve the loaded shapes. Instead the loaded shapes can be retrieved through the REST interface.
Assuming you are running the server and workbench locally, and the repository ID you
want to use is 1, you can use the following URL to download your shapes as RDF-XML:
http://localhost:8080/rdf4j-server/repositories/1/statements?context=%3Chttp%3A%2F%2Frdf4j.org%2Fschema%2Frdf4j%23SHACLShapeGraph%3E
All transactions are validated before being committed. A validation error when uploading data in the workbench looks like this:
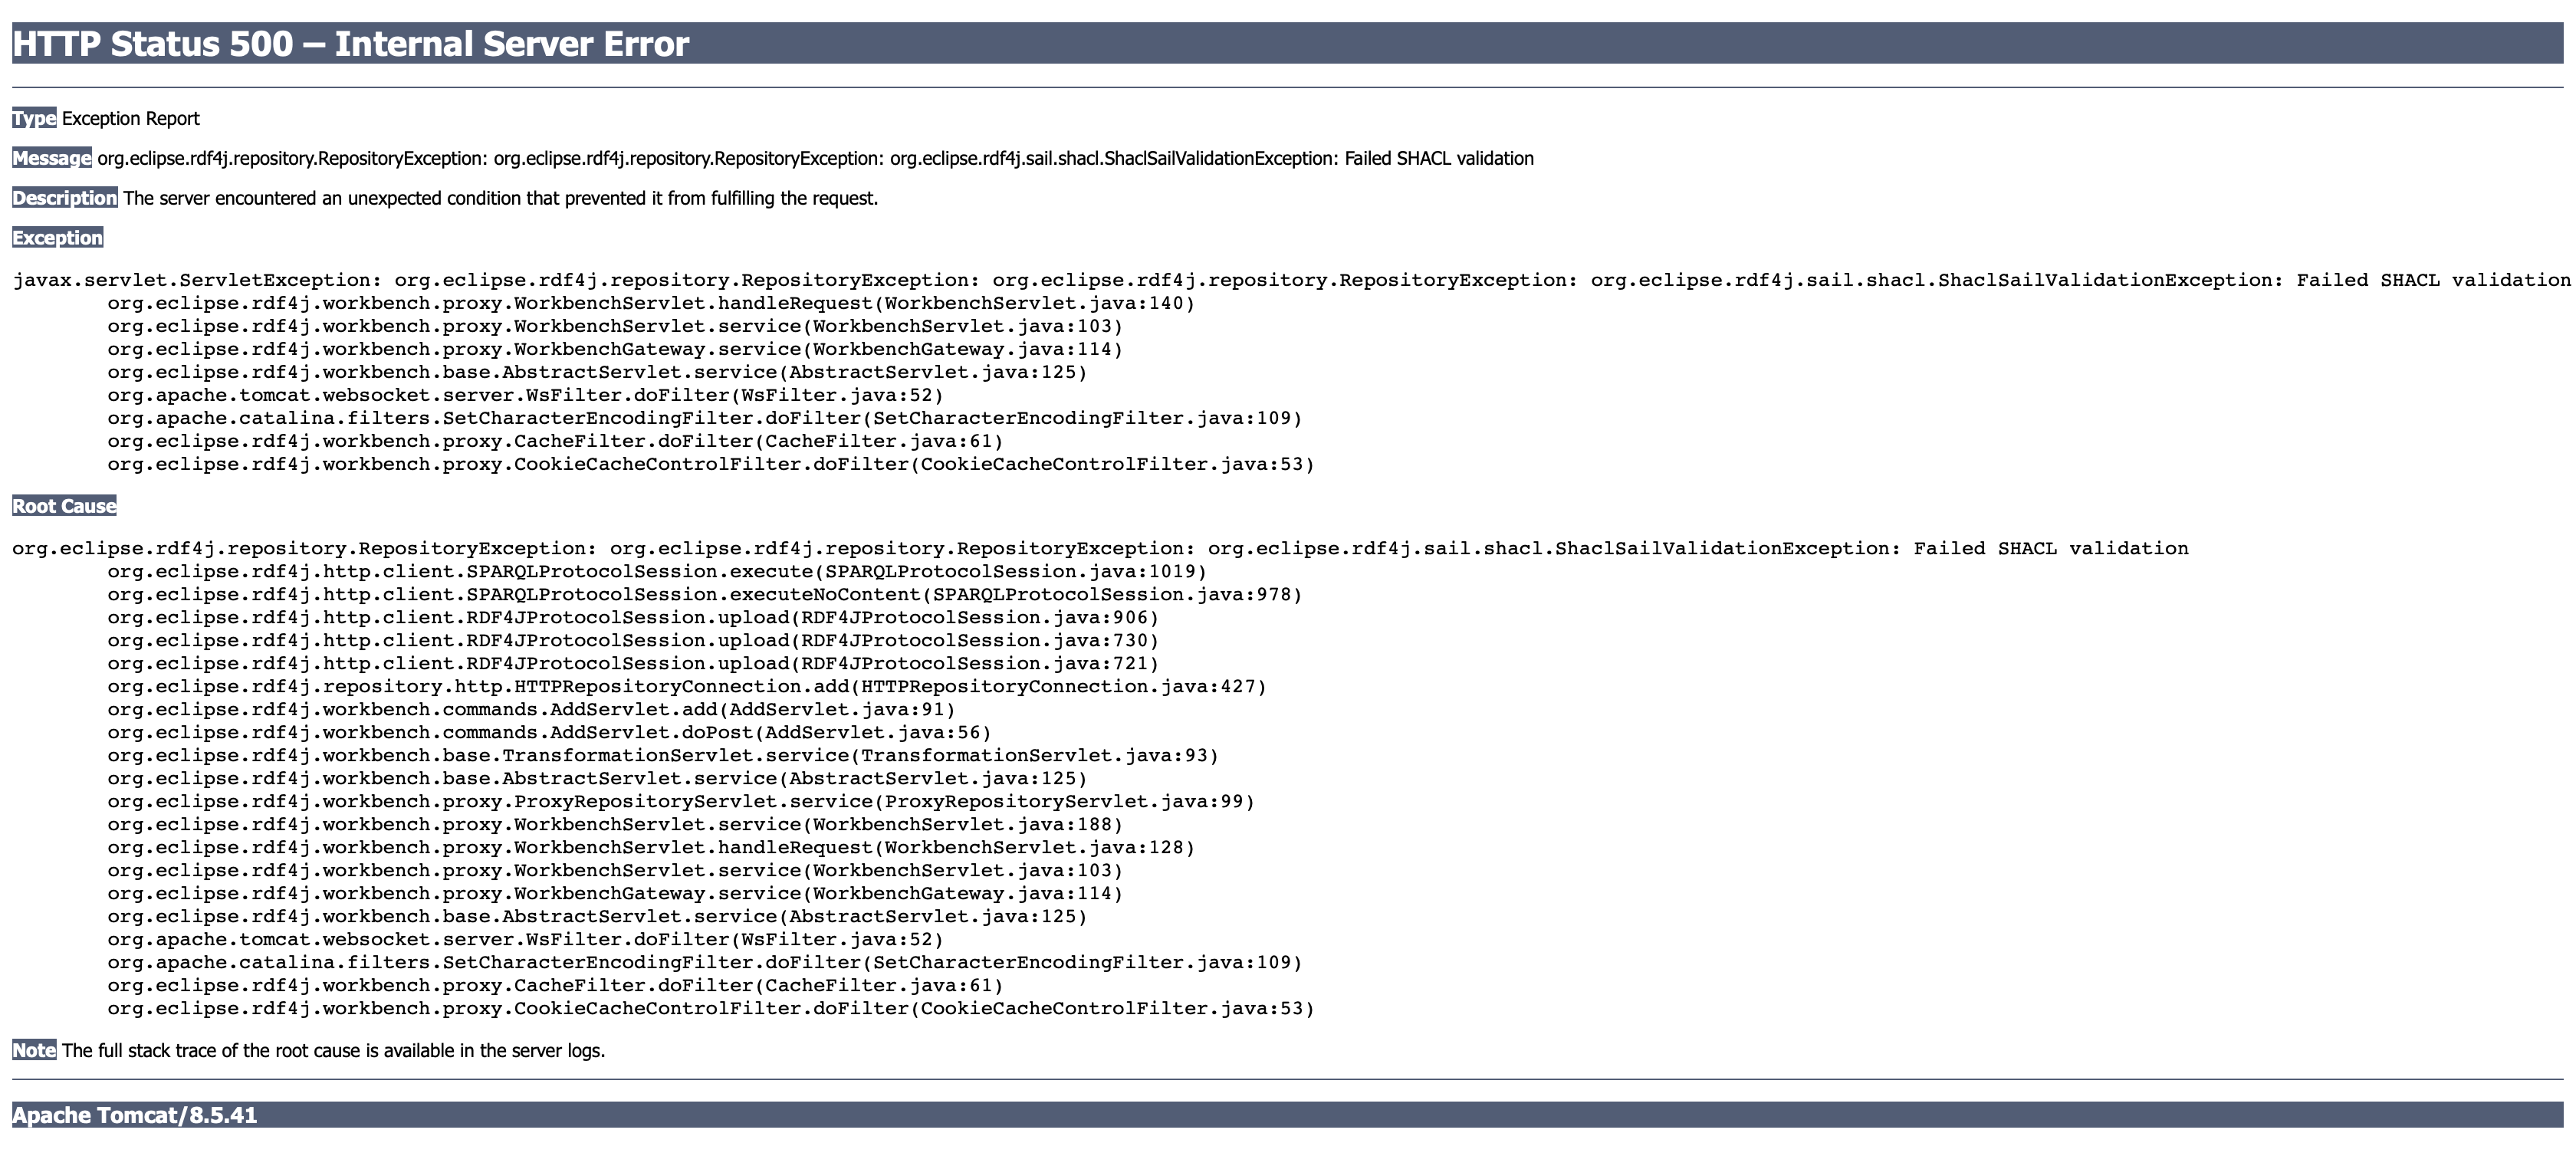
Your data will only be committed if it passes validation.
For a list of supported features and more info on how to use SHACL - see Programming with SHACL.
NOTE: since RDF4J 3.1
RDF4J integrates federation support using the FedX engine.
A federation can be configured from the RDF4J Workbench UI by picking the federation members. Once configured it can be used to explore or query the data of the federation members as a virtually integrated graph.
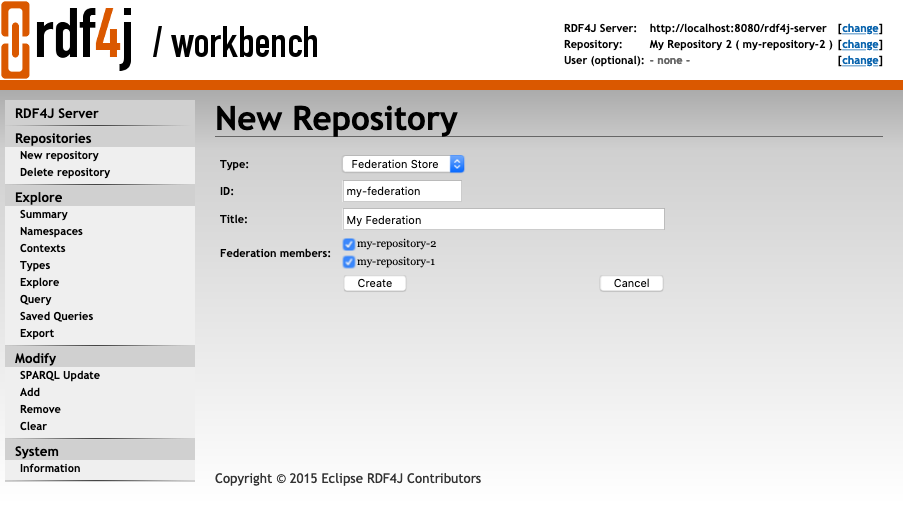
See Federation with FedX for more information.
Table of Contents